Writing
Resample text to sound like me
Remove watermarking and style transfer with LoRA
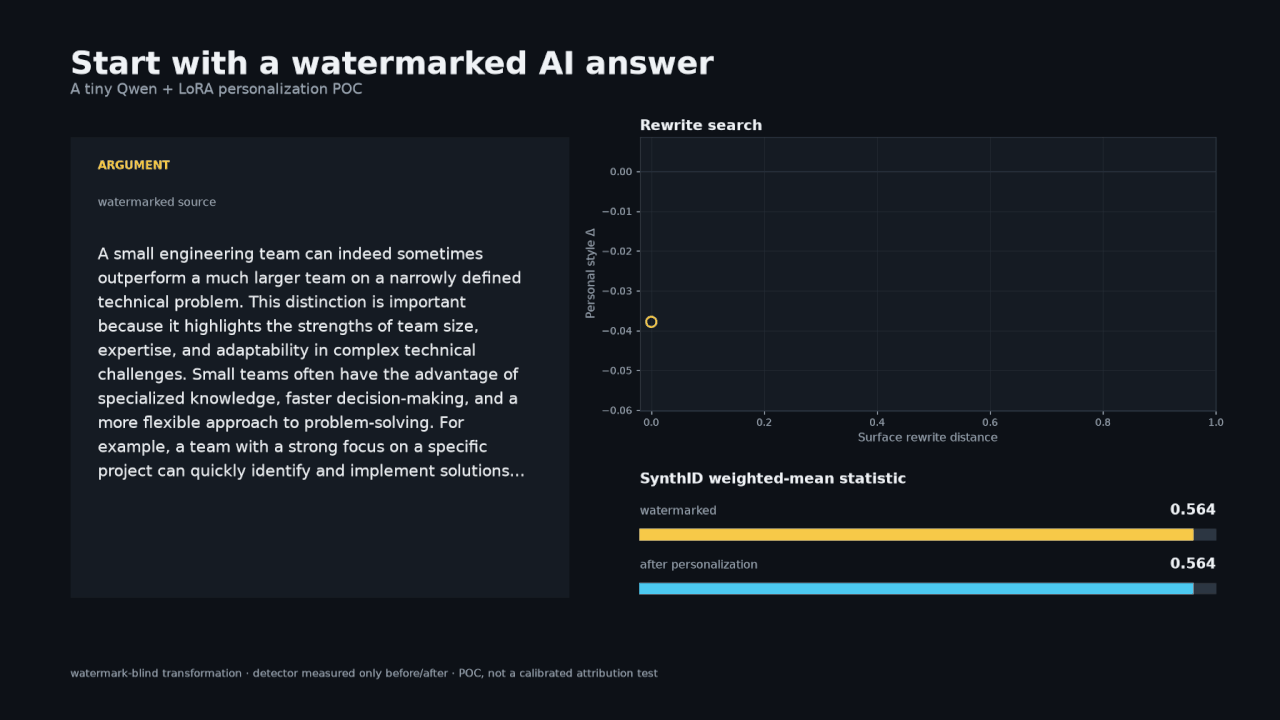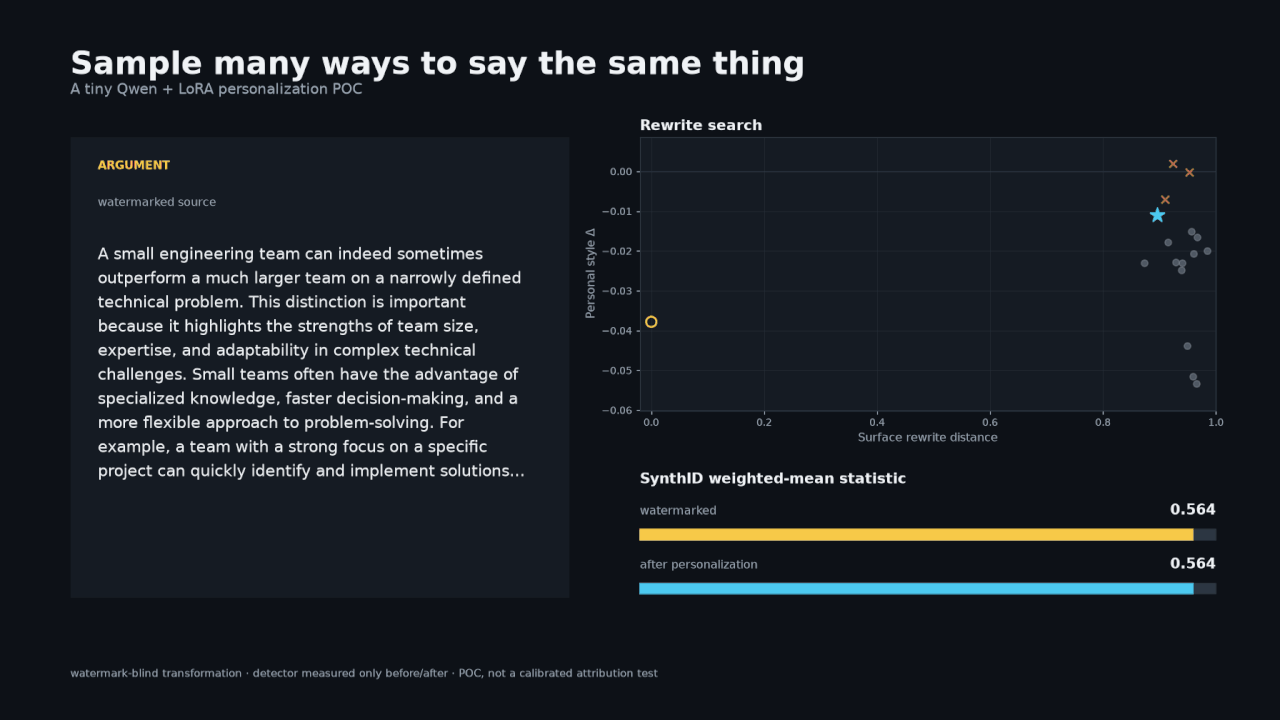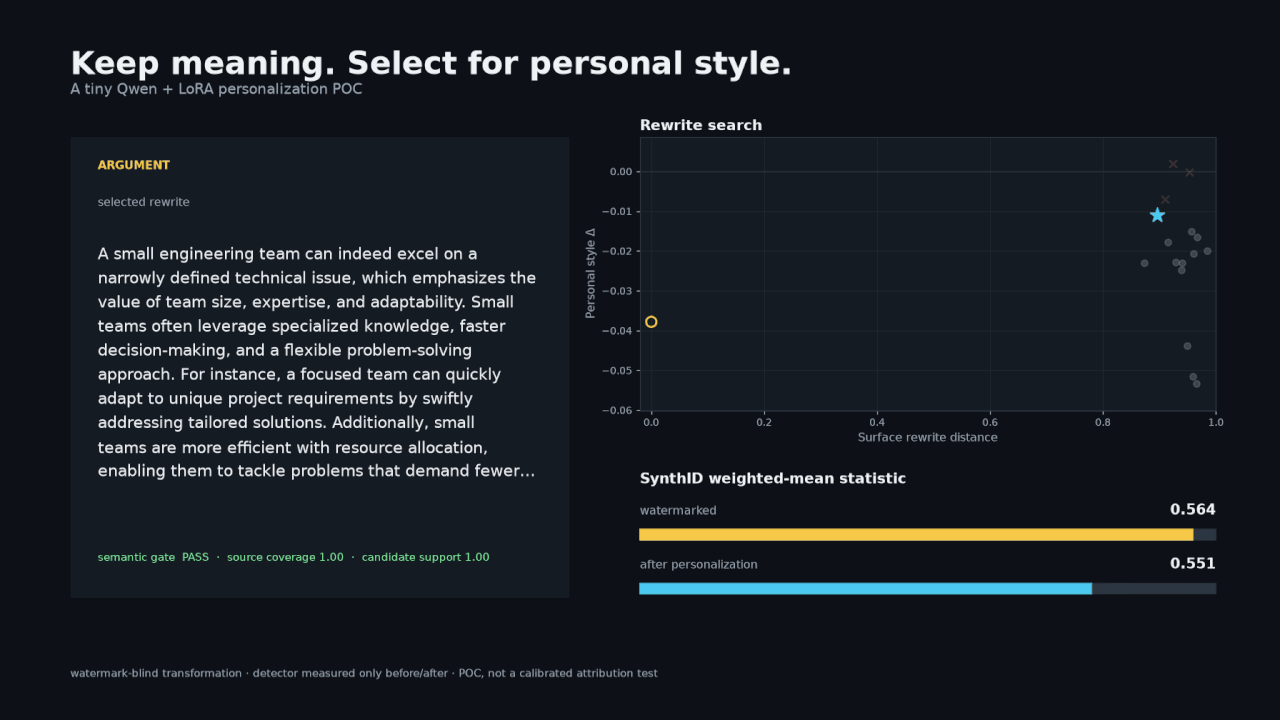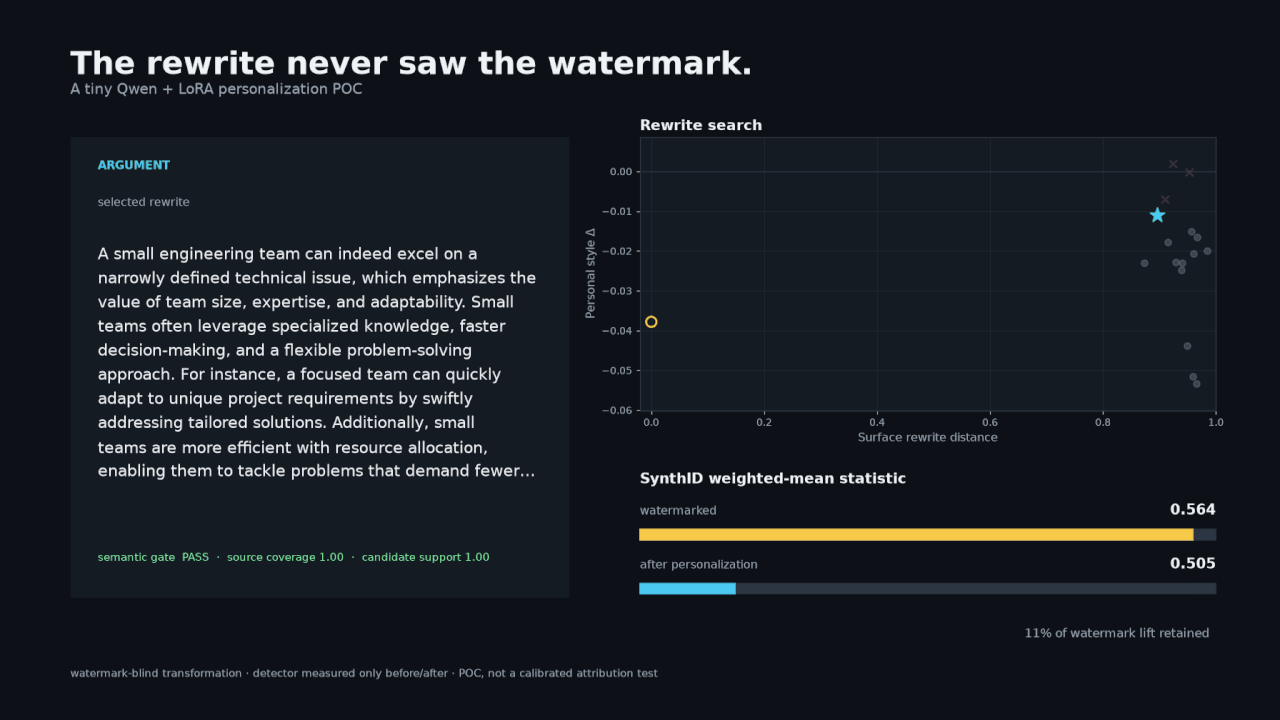
A lot of people are concerned about AI style and watermarking. So I did an experiment, I used LoRA to do style transfer from a small sample of my old blogs. What I found is that by doing this instead of sounding like an LLM you can not only attenuate the watermarking signal, you can also sound like a physicist who needs lexapro. This is not a threat model, Anthropic, please don't email me.
The setup is straight-forward, gather a corpus of your own text, ideally pre LLM era. For me that was a series of covid era blog posts on my GitHub. Get a baby sized qwen and use LoRA to bias away from post-training style and onto my own. Then I resample a bunch of rewrites without telling the model anything about my style, throw out any that drift too far in meaning from the source, and rank what's left by how "Paul" they sound via the fine-tuned model.
To test I chose a null, just give the model some samples of my writing and then ask to make the input text sound like me. This was the result
SOURCE: AI text detectors generally exploit statistical regularities...
"MAKE THIS SOUND LIKE ME": I've been learning about physics, and I think it's like looking into the mind of god. Whatever nihilistic temperament...
Harsh but fair.
However the resampler did a fine job, although apparently if you want to sound like me you need to lose a bit of semantic fidelity. Now interestingly I added Google DeepMind's SynthID watermarking to the input and personalization modified the statistical signal down (but so did paraphrasing, but that doesn't help the rhetoric).